


Google DeepMind
ER 1.6AvailableGemini Robotics-ER 1.6
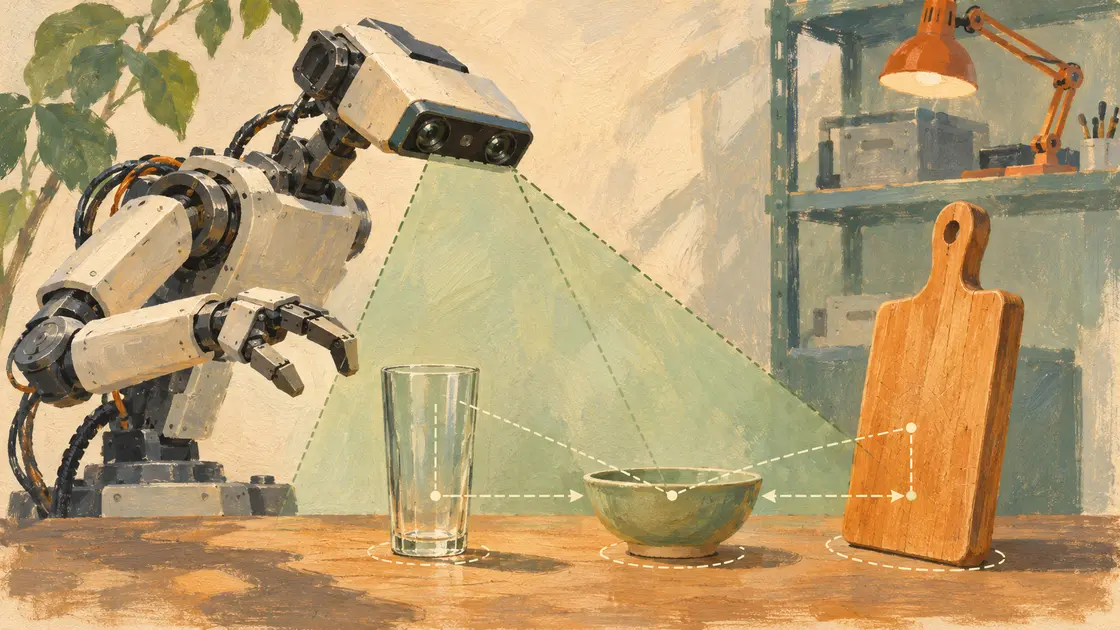
Google DeepMind's vision-language model for embodied reasoning. Interprets complex visual data, performs spatial reasoning, and plans multi-step actions from natural-language commands. Calls digital tools (Google Search, robot APIs) and delegates motor control to vision-language-action models. Available via the Gemini API in Google AI Studio.
About this model
Gemini Robotics-ER 1.6 (released 2026-04-15) is the current SOTA vision-language model for embodied reasoning. It produces precise 2D points for objects, plans multi-step missions from natural-language prompts, and natively calls tools — including third-party VLA models for motor control. In an Avala Physical AI pipeline, ER 1.6 can be used as a grounding model for high-level scene understanding and as a planner that coordinates downstream VLA or specialized perception models. Accessible to developers via the Gemini API. Builds on the Gemini Robotics research line (March 2026 paper).
Plan the integration path
Avala batch inference currently supports SAM and YOLO. For other catalog models, use the provider workflow and connect compatible prediction outputs where supported.
Review inference support →Capabilities
Task Types
Modalities